Google’s Data Agent Kit Hits GA, Splitting Agent Guardrails Between Skills and IAM
Google has made Data Agent Kit generally available, a free set of MCP tools and 37 open source skills that connect coding agents to more than fifteen Google Data Cloud services. Two kinds of guardrail ship with it, and practitioners need to tell them apart: one is a skill asking the agent to stop, the other an IAM…
Google recently made Data Agent Kit generally available, moving it out of the preview it ran through the summer. It is free, it is open source, and it installs into coding agents Google does not own. It ships two kinds of control, and the difference matters in production.
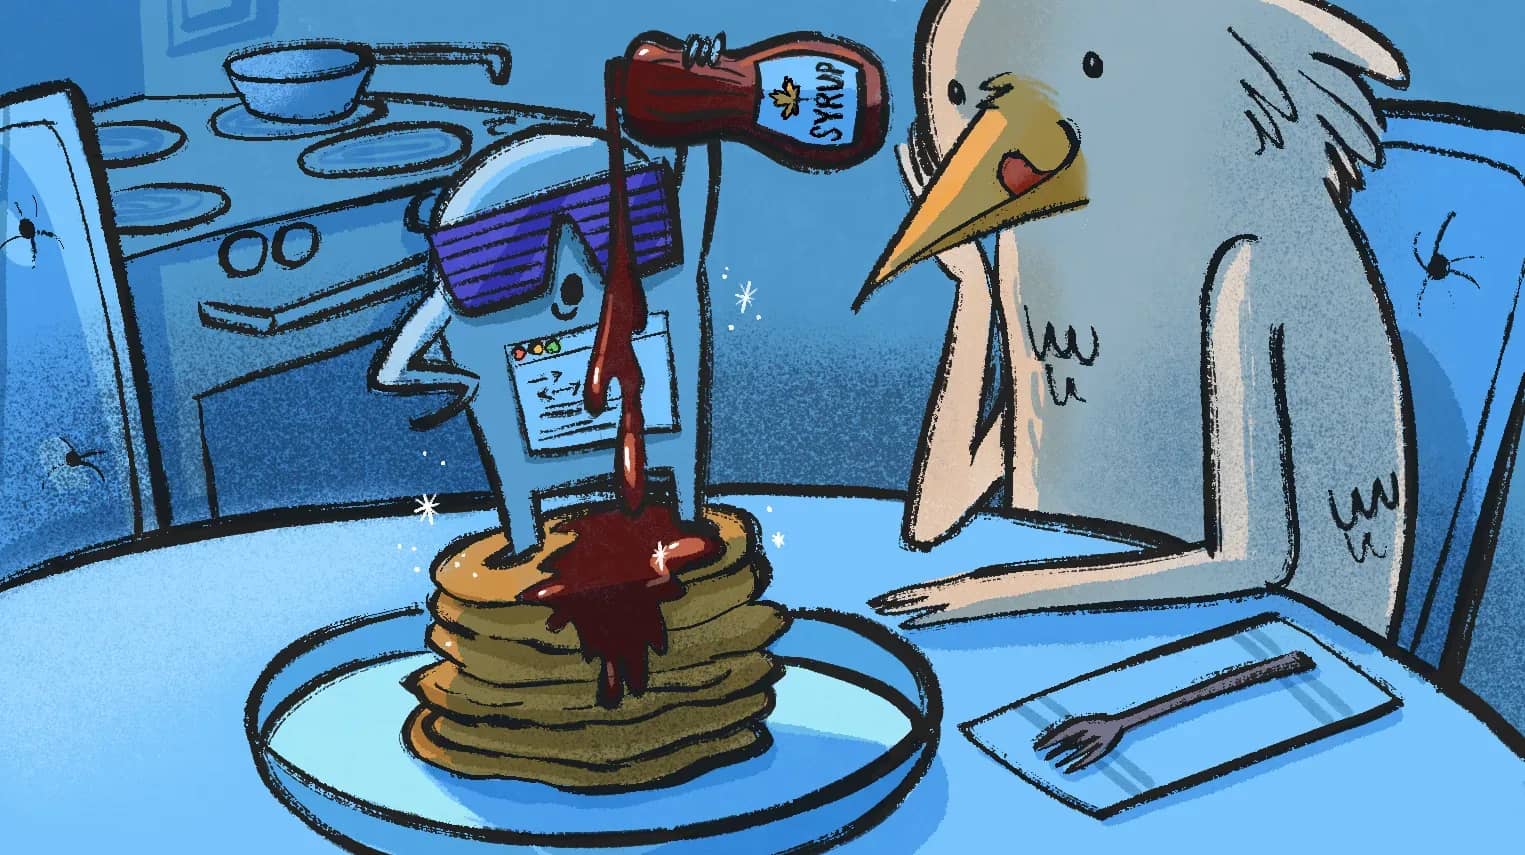
Data Agent Kit is a set of MCP tools connecting an agent to more than fifteen Google Data Cloud services, plus Google-authored skills that teach it practices like optimizing BigQuery SQL or designing Bigtable row keys. It runs in Antigravity, Claude Code, Codex, Cursor, and VS Code-compatible editors, and comes preinstalled in Cloud Shell and Cloud Workstations.
Data Agent Kit sits between the coding agent and Google Data Cloud services as two components: skills carrying best-practice guidance and MCP servers exposing live schema and tools. (Source: Google Blog post)
With the GA release, the company adds BigQuery Graph, Bigtable, and Managed Service for Apache Spark. Product manager Arun Nair and developer advocate Jeff Nelson, who wrote the launch post, pitch it at a gap agents have by default: they write good SQL but know nothing about "which tables exist, how they’re partitioned, which ones your team trusts, or why last night’s job failed."
The plugin repository carries 37 skills under Apache 2.0, each with frontmatter naming Google as publisher. It is versioned properly, with 1.0.0 cut on September 29 and 1.1.0 on October 13, so teams can pin it.
Among those skills is accidental-data-loss-prevention, which exists to stop the agent destroying something. Its description opens "STOP AND VERIFY" and tells the agent it "MUST obtain explicit user consent" before anything irreversible, listing DROP TABLE, TRUNCATE, a DELETE missing a WHERE clause or using 1=1, storage deletions against production buckets, gcloud projects delete, and KMS key destruction. The procedure is halt, explain the impact, wait for affirmative consent.
That guardrail is advice. The agent is asked to obey it. A second control is not.
Asked in a LinkedIn post whether read-only investigation could be isolated from tools that modify infrastructure, Nelson answered that it is handled in IAM rather than per agent: run the agent as a read-only service account through impersonation, or use "an IAM deny policy that blocks any MCP tool where tool.isReadOnly is false."
The documentation gives the condition:
api.getAttribute('mcp.googleapis.com/tool.isReadOnly', false) == false
It denies the mcp.googleapis.com/tools.call permission, and applies at the organization, folder, or project level. Companion attributes cover resource.service and tool.name.
Three limits come with it. A blocked tool still appears in tools/list, so the agent sees capabilities it cannot use and finds out only on invocation. The controls cover Google Cloud MCP servers and nothing else. And resource.service and tool.name are gcloud only, absent from the console.
Amel Habira, an AI solutions architect, read the documentation and came away encouraged, noting the short-lived credentials, the read-only attribute, and a warning before agents execute notebook cells. He wrote:
Combine that with branching and time travel on the Iceberg side, and you can imagine containment at both the access layer and the data layer.
Ankit Dongre, an AI engineer at viaSocket, drew the boundary further out:
MCP access is the easy part. The production boundary is permission scope plus repeat-safe execution: what happens when an agent retries a write after a timeout, or when the schema changes mid-run?
IAM and dry runs cover authorization and preflight, he added, "but they do not tell the agent whether a timed-out write committed. A first-class result should carry an idempotency key plus commit status and rollbackability." Data Agent Kit’s tool results do not carry that today.
Microsoft put that decision somewhere else. Its Agent 365 integration with Azure API Management, in public preview, keeps governance intent in a Microsoft 365 admin surface and enforces it at a gateway, where per-tool blocking requires a preview tier and the application key is "gateway-scoped", reaching every model and tool. Google authorizes per tool in the IAM language customers already use, and propagates the user’s identity so row and column security applies.
Operators are sequencing either way carefully. Timon Knapp, founder of the self-hosted workload automation vendor Conductral, wrote:
Connecting agents to live environments like Airflow is powerful. From running production batch for years I would start with read access and suggestions, and let a human confirm anything that changes a schedule or reruns a job. A clean audit trail makes it much easier to give the agent more rights later.
Data Agent Kit costs nothing beyond the Google Cloud services an agent uses. The skills are on GitHub and forkable.
Originally published on
InfoQ
Keep reading
 Fly.io Blog