Memory-Enforced GPU Sharing in Kubernetes with NVIDIA CUDA 13.4
Many AI workloads need only a fraction of a GPU. Giving each one an entire device can leave capacity idle; sharing GPUs lets platform teams serve more workloads...
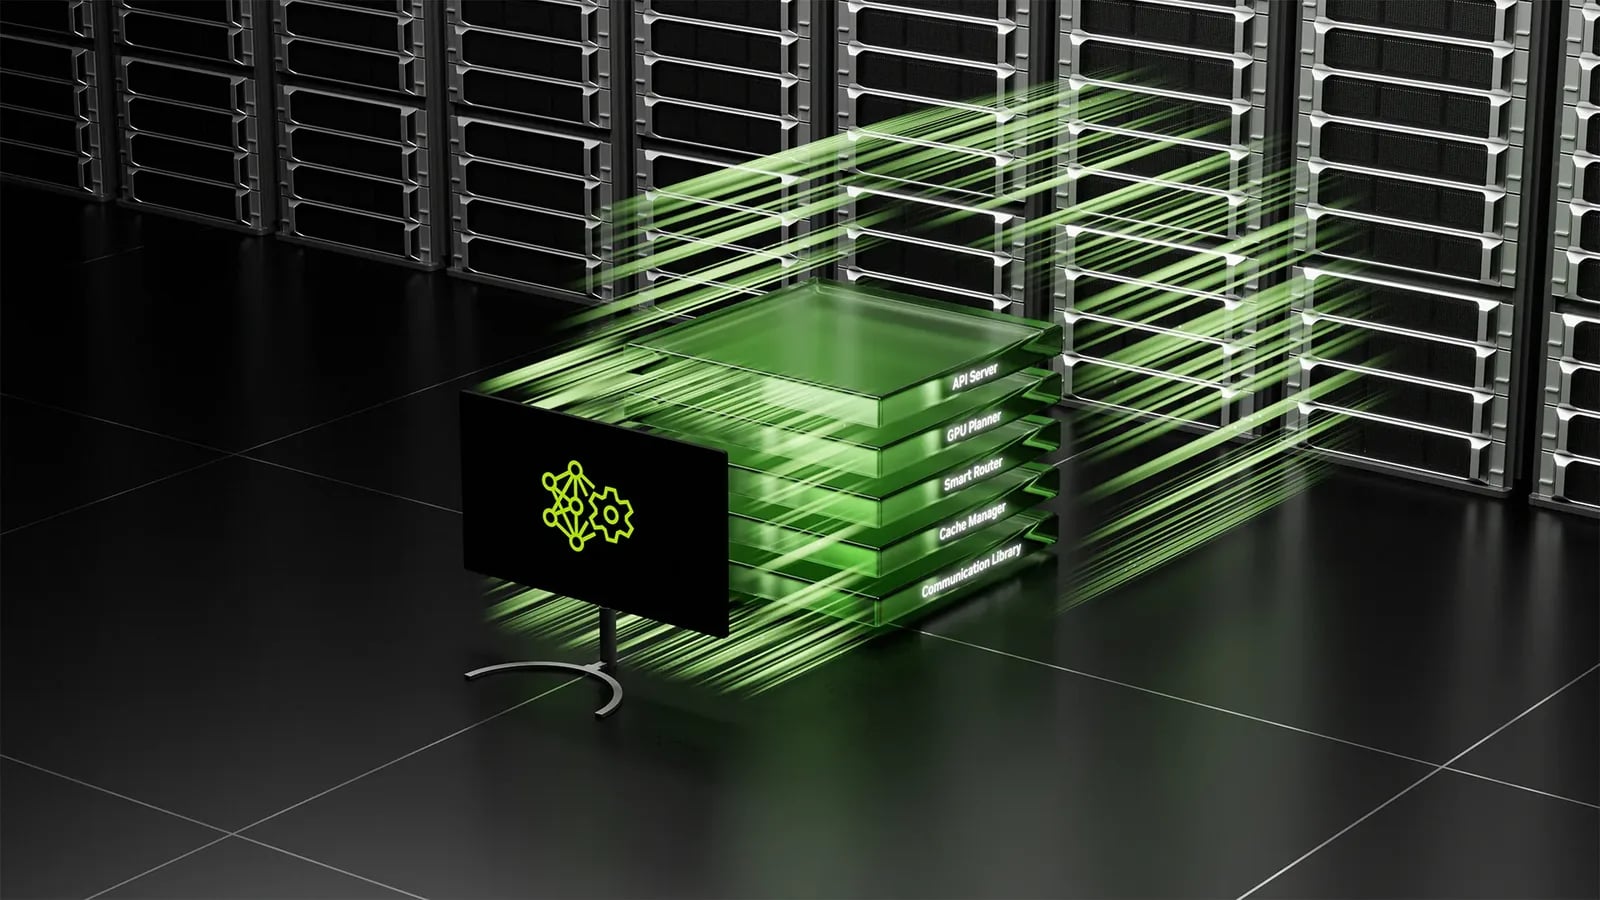
Many AI workloads need only a fraction of a GPU. Giving each one an entire device can leave capacity idle; sharing GPUs lets platform teams serve more workloads with the infrastructure they already have.
NVIDIA GPUs already support several approaches to sharing. Multi-instance GPU (MIG) splits a GPU into hardware-isolated instances that are transparent to the application, time-slicing lets several processes take turns without memory enforcement, and Multi-Process Service (MPS) lets them run concurrently in separate address spaces (sm-sharing).
CUDA 13.4 now enforces a memory boundary that is transparent to the application with a new time-sharing mode, alongside the compute sharing mode (sm-sharing) that already existed in MPS.
Here is what the CUDA release brings:
خواندن NVIDIA Technical Blog با پرو
این منبع جزو کتابخانه پرو است. همه منابع ویژه، ترجمه هوشمند و فیدهای شخصی را باز کنید.
منتشرشده در
NVIDIA Technical Blog
ادامه مطالعه
 Kubernetes Blog
 Netflix TechBlog
 Netflix TechBlog