Run AI Models for Edge Application Development with Just a Few Commands
AI is expanding beyond the data center as developers build a new generation of agents to act at the edge: monitoring driver attention and cabin conditions,...
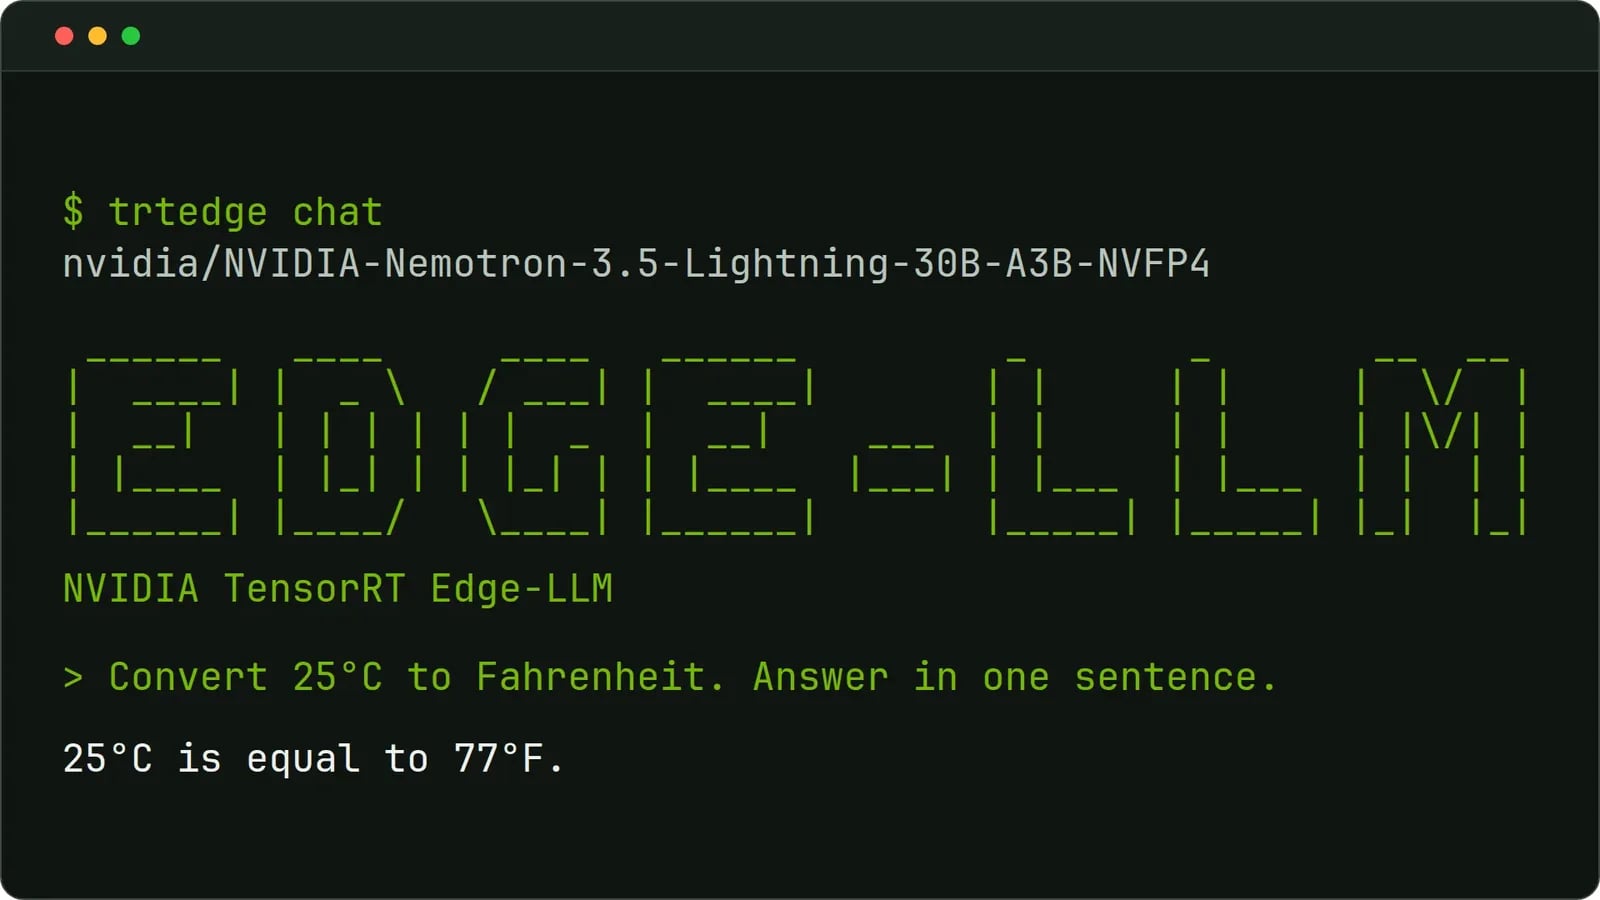
AI is expanding beyond the data center as developers build a new generation of agents to act at the edge: monitoring driver attention and cabin conditions, helping robots understand their surroundings and plan tasks, and coordinating fleets of machines on production lines. These physical AI applications rely on models that perceive, reason, and act within tight memory, power, and latency budgets. But getting a model ready to run can involve substantial setup.
NVIDIA DGX Spark, now available in a 64GB configuration, gives embedded developers a platform to prototype, fine-tune, and test models and agents. NVIDIA TensorRT Edge-LLM provides a lightweight C++ inference runtime designed for embedded workloads, bringing the same inference framework to development on Spark and deployment on platforms such as NVIDIA Jetson Thor, NVIDIA DRIVE AGX Thor, and NVIDIA IGX Thor.
You can get started in just a few commands with the trtedge command-line interface (CLI). It downloads your selected model and builds TensorRT engines optimized for inference on Spark.
In this tutorial, you’ll run NVIDIA Nemotron-3.5 Lightning, a text-only model, on Spark using TensorRT Edge-LLM. You’ll test prompts in your terminal and serve the model through an API for application prototyping. You’ll also enable DSpark speculative decoding to accelerate generation.
خواندن NVIDIA Technical Blog با پرو
این منبع جزو کتابخانه پرو است. همه منابع ویژه، ترجمه هوشمند و فیدهای شخصی را باز کنید.
منتشرشده در
NVIDIA Technical Blog
ادامه مطالعه
 Supabase Blog