Skip to content

برچسب

#PyTorch

۱۱ مقاله

PBPyTorch Blog

Muse Spark 1.2 Is Now Open Weights

Today, Meta is releasing the weights for Muse Spark Open, the most capable US open weights model to date. It’s available today on Hugging Face under the Muse Model License. Muse... The post Muse Spark 1.2 Is Now Open Weights appeared first on PyTorch .

هوش مصنوعی۴ دقیقه مطالعه
PBPyTorch Blog

Bringing ExecuTorch to Arm Cortex-M CPUs

TL;DR Deploying PyTorch models on microcontrollers has historically required converting to other framework formats, maintaining separate toolchains, and debugging cross framework numerical mismatches. ExecuTorch eliminates this conversion step entirely. The Cortex M... The post Bringing ExecuTorch to Arm Cortex M…

هوش مصنوعی۱۰ دقیقه مطالعه
PBPyTorch Blog

Extending Inductor for the IBM Spyre Accelerator

TL;DR The PyTorch based software stack for IBM’s Spyre accelerator recently moved its torch.compile backend from sendnn, a separate compilation stack built entirely from scratch, to backend=inductor, an open source backend built... The post Extending Inductor for the IBM Spyre Accelerator appeared first on PyTorch .

هوش مصنوعی۱۷ دقیقه مطالعه
PBPyTorch Blog

Session-Aware Agentic Inference with NVIDIA Dynamo

TL;DR Agentic workloads change the traffic an inference server sees. Unlike single turn chat, an agent session can involve a large initial prefill, repeated model calls, and subagents running in parallel,... The post Session Aware Agentic Inference with NVIDIA Dynamo appeared first on PyTorch .

هوش مصنوعی۱۶ دقیقه مطالعه
PBPyTorch Blog

Building Spyre as a Native PyTorch Device

TL;DR Spyre becomes a native PyTorch device by connecting PyTorch’s existing device, allocator, stream, and compiler abstractions through torch spyre to the Spyre runtime and firmware. PrivateUse1 gives Spyre a real... The post Building Spyre as a Native PyTorch Device appeared first on PyTorch .

هوش مصنوعی۲۲ دقیقه مطالعه
PBPyTorch Blog

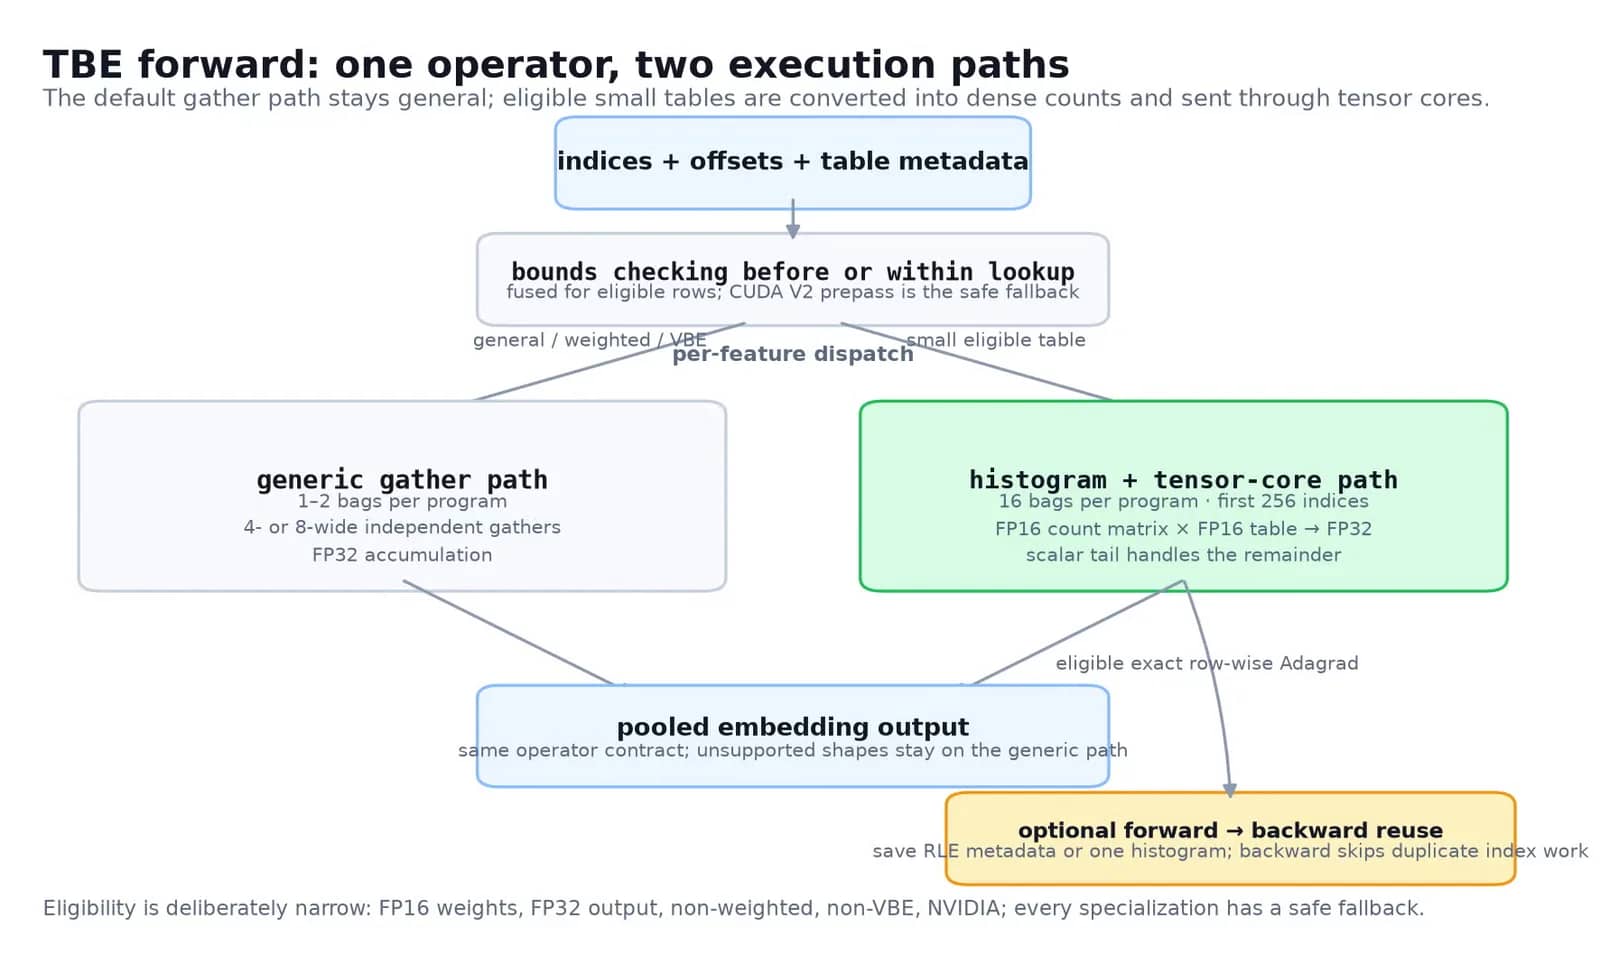
Modernizing Table Batched Embeddings with FBTriton

This post explores the FBTriton kernel design for Table Batched Embedding (TBE) forward and backward passes. These core operators handle embedding lookups across thousands of sharded GPUs within recommendation systems.... The post Modernizing Table Batched Embeddings with FBTriton appeared first on PyTorch .

هوش مصنوعی۹ دقیقه مطالعه
همه را دیدید ✓