Automating Data Ingestion with a RAG Flywheel
Automating schema mapping for diverse supplier data using a RAG Flywheel and LLMs.
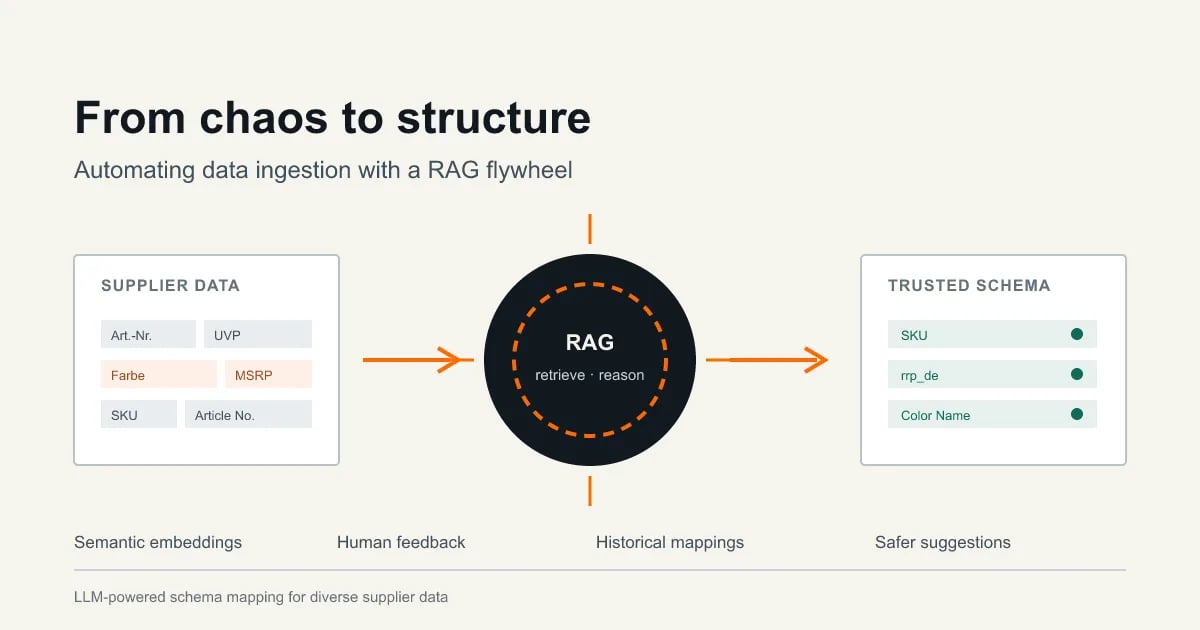
The Problem: The Schema Mapping Bottleneck
At Zalando, our Supply Operations team manages a vast array of supplier offers. Each supplier provides their data in different formats, structures, and schemas. This diversity creates a significant challenge for the data ingestion processes, as they need to map these varying schemas into a unified format that our systems can understand and process efficiently. For every uploaded file, operations specialists must manually map the highly diverse schemas (source headers/columns), ranging from 10-60 columns per sheet per workbook, with unpredictable variations in header naming conventions like "Art.-Nr.", "Article Number", "SKU", or "Farbe" (color in German) to our strictly defined internal target schema of over 55 columns (for example, SKU, Color Code, and Color Name).
Traditionally, automating this type of schema matching relied heavily on hardcoded rules, regular expressions, or Levenshtein distance-based fuzzy matching. However, these methods often fall short when dealing with the high variability and complexity of real-world data. The semantic meaning of a column such as Retail Price might appear under different names like UVP, Price, or MSRP. Since these legacy engines lack semantic understanding of the data, they tend not to scale with the growing diversity of supplier data and require continuous manual maintenance from engineers every time a new supplier is onboarded or an existing supplier changes its data format.
خواندن Zalando Engineering با پرو
این منبع جزو کتابخانه پرو است. همه منابع ویژه، ترجمه هوشمند و فیدهای شخصی را باز کنید.
منتشرشده در
Zalando Engineering
ادامه مطالعه
 Vercel Blog
 Supabase Blog