Bad benchmarks and evals: Senior SWE-Bench, napkin math, and winter tires
We're going to look at three different kinds of benchmarks, one set of calculations for baseline numbers for performance "napkin math" estimates, one set of AI model evals, and one on car tires. To build my intuition for things, I like thinking about them before seeing the explanation, so these are presented with the…
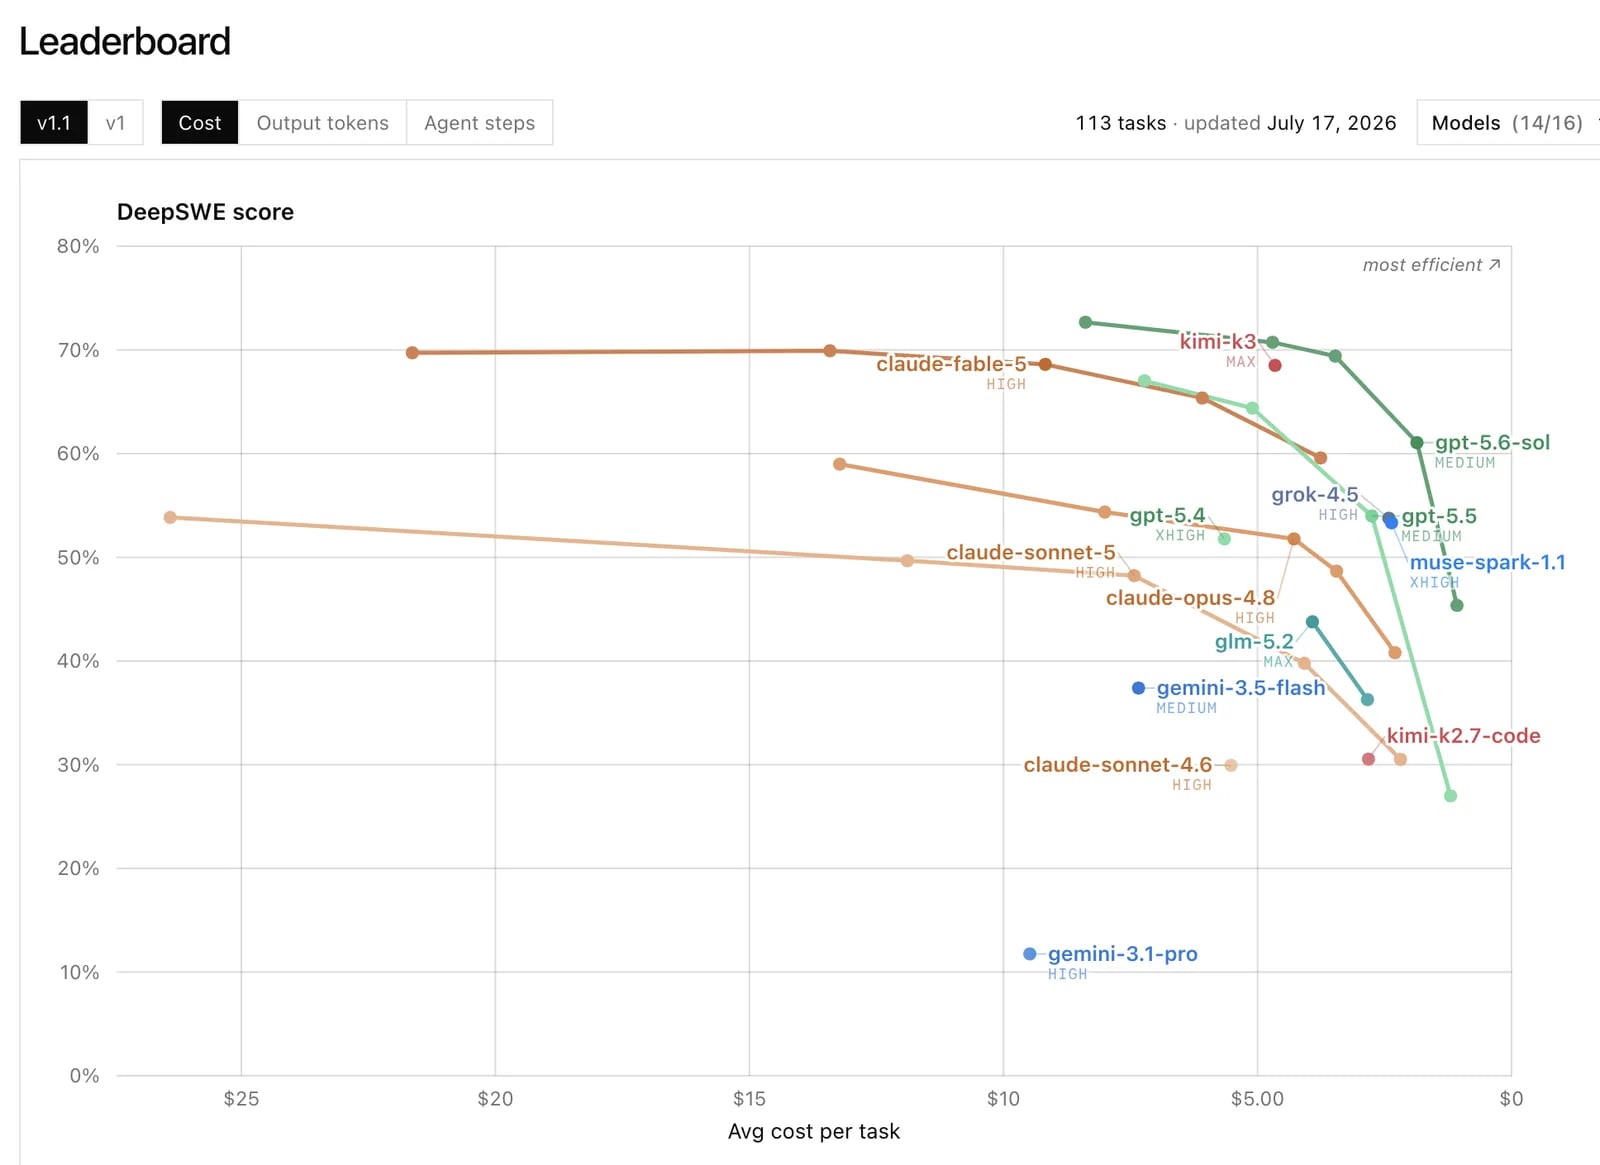
We're going to look at three different kinds of benchmarks, one set of calculations for baseline numbers for performance "napkin math" estimates, one set of AI model evals, and one on car tires. To build my intuition for things, I like thinking about them before seeing the explanation, so these are presented with the benchmark information first and the explanation later in case you want to think about your answer before seeing my thoughts.
29. A friend of mine is reviewing performance orders of magnitude to prep for computer performance interviews and found that https://github.com/sirupsen/napkin-math (5.4k stars) was the top hit. The README's tables include:
| Napkin Math performance estimates | ||||
| Operation | Latency | Throughput | 1 MiB | 1 GiB |
| Sequential Memory R/W (64 bytes) | 0.5 ns | |||
| ├ Single Thread | 20 GiB/s | 50 μs | 50 ms | |
| ├ Threaded | 200 GiB/s | 5 μs | 5 ms | |
| Network Same-Zone | 10 GiB/s | 100 μs | 100 ms | |
| ├ Inside VPC | 10 GiB/s | 100 μs | 100 ms | |
| ├ Outside VPC | 3 GiB/s | 300 μs | 300 ms | |
| Hashing, not crypto-safe (64 bytes) | 10 ns | 5 GiB/s | 200 μs | 200 ms |
| Random Memory R/W (64 bytes) | 20 ns | 3 GiB/s | 300 μs | 300 ms |
Fast Serialization [8] [9] † | N/A | 1 GiB/s | 1 ms | 1s |
Fast Deserialization [8] [9] † | N/A | 1 GiB/s | 1 ms | 1s |
| System Call | 300 ns | N/A | N/A | N/A |
| Hashing, crypto-safe (64 bytes) | 100 ns | 1 GiB/s | 1 ms | 1s |
| Sequential SSD read (8 KiB) | 1 μs | 8 GiB/s | 100 μs | 100 ms |
Context Switch [1] [2] | 10 μs | N/A | N/A | N/A |
| Sequential SSD write, -fsync (8KiB) | 2 μs | 3 GiB/s | 300 μs | 300 ms |
| TCP Echo Server (32 KiB) | 50 μs | 500 MiB/s | 2 ms | 2s |
| Random SSD Read (8 KiB) | 100 μs | 70 MiB/s | 15 ms | 15s |
Decompression [11] | N/A | 1 GiB/s | 1 ms | 1s |
Compression [11] | N/A | 500 MiB/s | 2 ms | 2s |
| Sorting (64-bit integers) | N/A | 500 MiB/s | 2 ms | 2s |
| Proxy: Envoy/ProxySQL/Nginx/HAProxy | 50 μs | ? | ? | ? |
| Network within same region | 250 μs | 2 GiB/s | 500 μs | 500 ms |
| Premium network within zone/VPC | 250 μs | 25 GiB/s | 50 μs | 40 ms |
| Sequential SSD write, +fsync (8KiB) | 300 μs | 30 MiB/s | 30 ms | 30s |
| {MySQL, Memcached, Redis, ..} Query | 500 μs | ? | ? | ? |
Serialization [8] [9] † | N/A | 100 MiB/s | 10 ms | 10s |
Deserialization [8] [9] † | N/A | 100 MiB/s | 10 ms | 10s |
| Sequential HDD Read (8 KiB) | 10 ms | 250 MiB/s | 2 ms | 2s |
| Random HDD Read (8 KiB) | 10 ms | 0.7 MiB/s | 2 s | 30m |
| Blob Storage GET, if-not-match 304 | 30 ms | |||
| Blob Storage GET, 1 conn (128KiB) | 80 ms | 100 MiB/s | 10 ms | 10s |
| Blob Storage GET, n conn (offsets) | 80 ms | NW limit | ||
| Blob Storage LIST | 100 ms | |||
| Blob Storage PUT, 1 conn (128KiB) | 200 ms | 100 MiB/s | 10 ms | 10s |
| Blob Storage PUT, n conn (multipart) | 200 ms | NW limit | 10 ms | 10s |
Network between regions [6] | Varies | 25 MiB/s | 40 ms | 40s |
| Network NA Central <-> East | 25 ms | 25 MiB/s | 40 ms | 40s |
| Network NA Central <-> West | 40 ms | 25 MiB/s | 40 ms | 40s |
| Network NA East <-> West | 60 ms | 25 MiB/s | 40 ms | 40s |
| Network EU West <-> NA East | 80 ms | 25 MiB/s | 40 ms | 40s |
| Network EU West <-> NA Central | 100 ms | 25 MiB/s | 40 ms | 40s |
| Network NA West <-> Singapore | 180 ms | 25 MiB/s | 40 ms | 40s |
| Network EU West <-> Singapore | 160 ms | 25 MiB/s | 40 ms | 40s |
What's wrong with this benchmark?
خواندن Dan Luu با پرو
این منبع جزو کتابخانه پرو است. همه منابع ویژه، ترجمه هوشمند و فیدهای شخصی را باز کنید.
منتشرشده در
Dan Luu
ادامه مطالعه