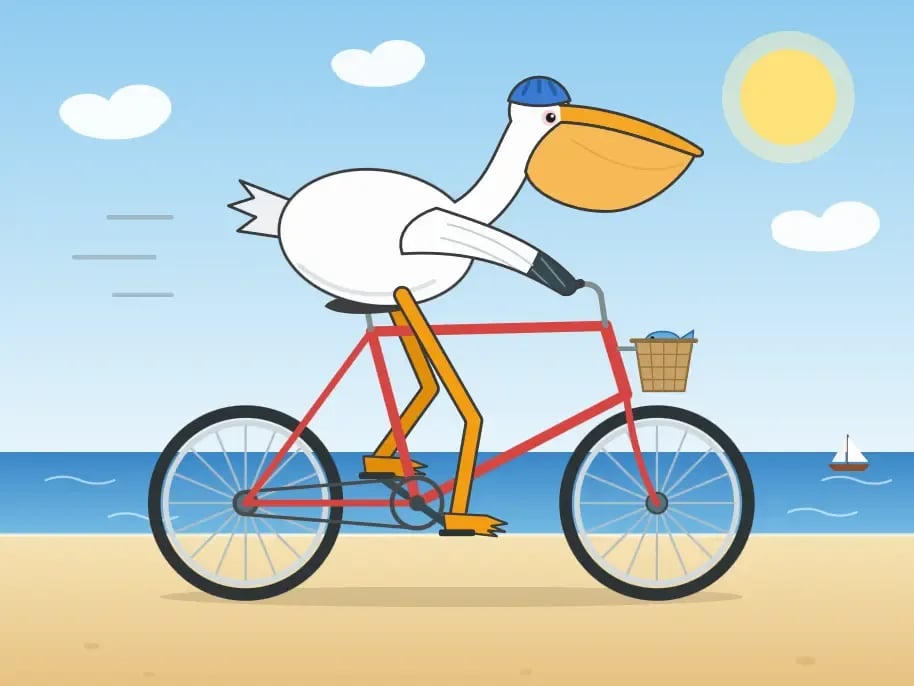
Claude Fable 5.1 made me a really nice animated pelican
Today is Claude Fable (and Mythos) 5.1 day . Anthropic say that Fable 5.1 "sets a new standard for coding, knowledge work, and long running problem solving tasks". Their announcement spends a notable amount of time on scientific research, boasting of a 52.6% score on the brand new Terminal Bench Science 0.1 benchmark…
1st September 2026
Today is Claude Fable (and Mythos) 5.1 day. Anthropic say that Fable 5.1 “sets a new standard for coding, knowledge work, and long-running problem-solving tasks”. Their announcement spends a notable amount of time on scientific research, boasting of a 52.6% score on the brand new Terminal-Bench-Science 0.1 benchmark (first announced on August 27th), up from 24.7% for Fable 5, 29.0% for Opus 5 and 22.4% for GPT-5.6 Sol. Other benchmarks show slightly improved scores, but none as impressive as the Science one.
But how well can it pelican?
Back in July I wrote about how I was losing faith in the pelican benchmark—its connection to how good the models were at other tasks didn’t seem to hold as strongly as it did back in 2025. The most interesting insights I get from it now are comparisons within model families, and particularly comparisons for the same prompt at different reasoning effort levels.
خواندن Simon Willison با پرو
این منبع جزو کتابخانه پرو است. همه منابع ویژه، ترجمه هوشمند و فیدهای شخصی را باز کنید.
منتشرشده در
Simon Willison
ادامه مطالعه
 Cloudflare Blog
 Anthropic