Skip to content

Tag

#Benchmarks

37 articles

ReviewBench: An open benchmark for AI code review

We’re launching ReviewBench, a benchmark for code review agents built on representative GitHub pull requests, multi source ground truth, calibrated evaluation, and production aligned metrics. The post ReviewBench: An open benchmark for AI code review appeared first on The GitHub Blog .

AI & ML9 min read
Uber Engineering

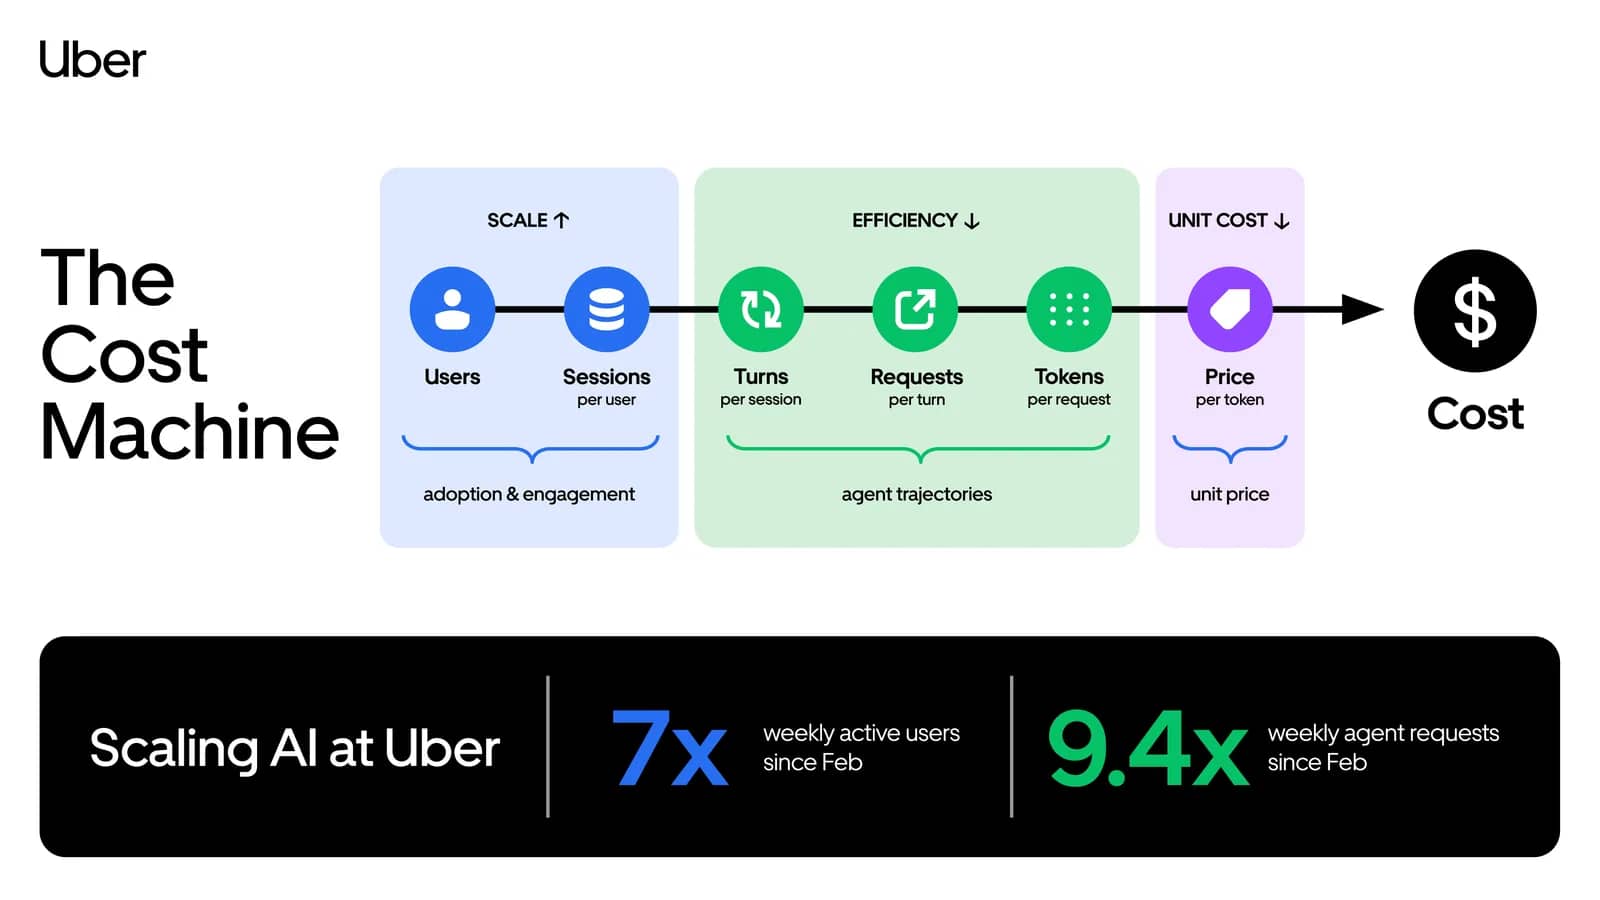
Running a Software Factory Efficiently at Uber Scale

We just published a deep dive on how we keep AI coding costs under control at Uber, even as usage keeps climbing. Since February, weekly active employees across all functions on our agentic offerings grew 7x, and weekly agent requests grew 9.4x. Over that same stretch, total spend has relatively stabilized. We broke…

AI & ML14 min read
Vercel Blog

How Ora benchmarks every major AI agent on Vercel

Ora on Vercel Front end, back end, and agent runtime on one platform Every major agent tested side by side on live sites Hundreds of commits a day from a 16 person engineering team Ora sends agents onto live websites with instructions to sign up for a product, integrate with it, and pay for it. Agents often fail, and…

AI & ML5 min read
JAJetBrains AI

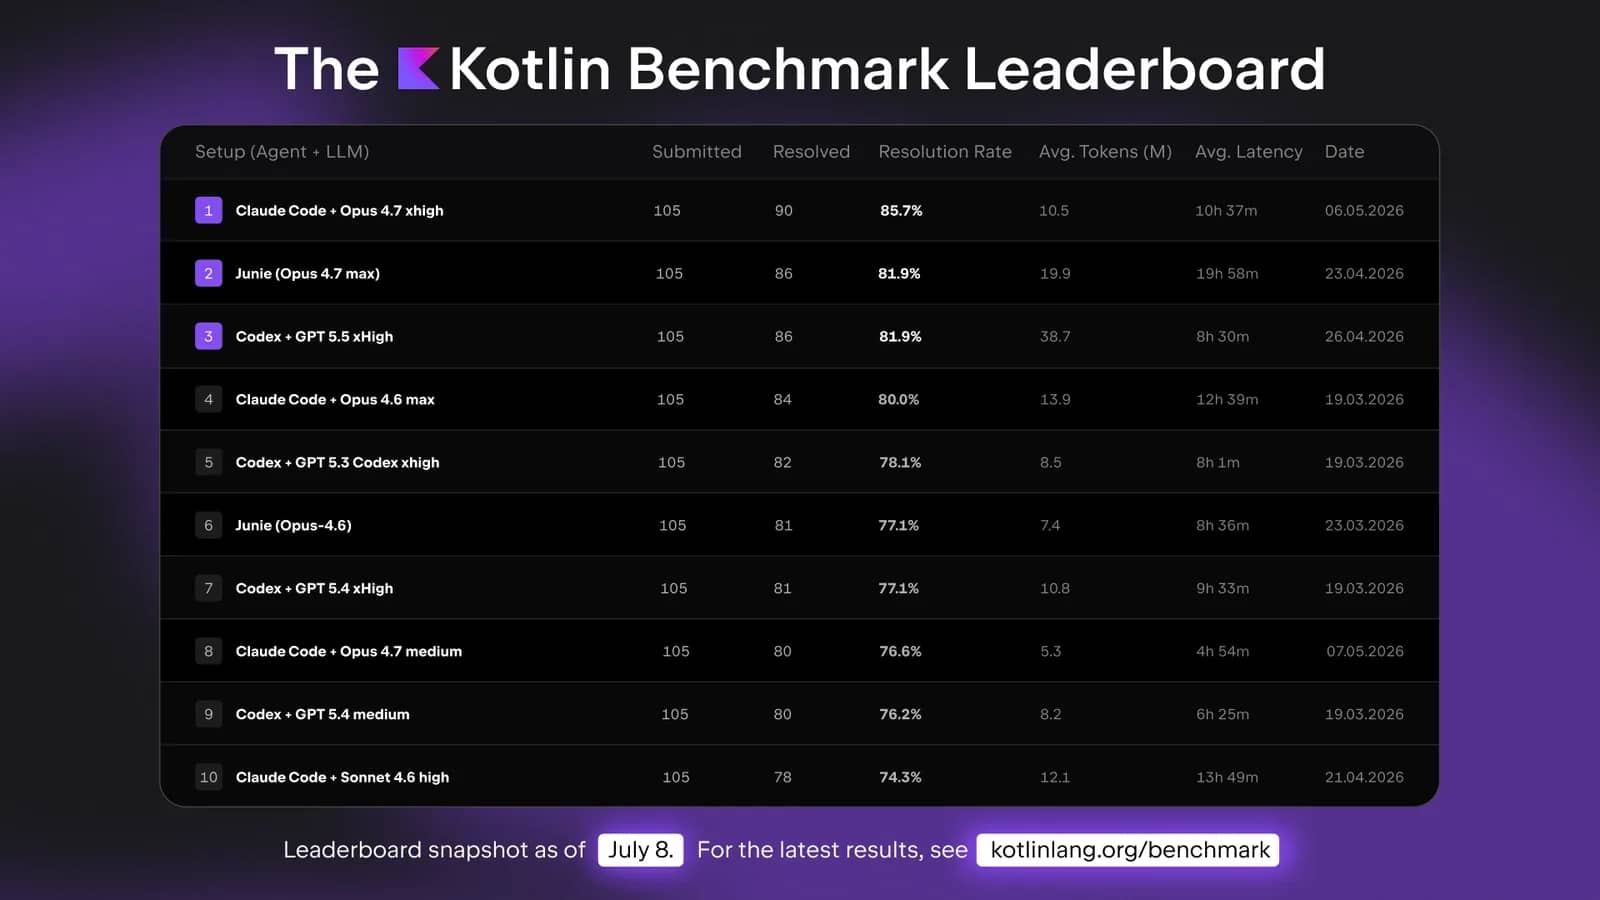
Introducing the Kotlin Benchmark for AI Coding Agents

Agentic coding benchmarks are getting closer to real world software development. For Kotlin teams, the most important question is how reliably AI agents can complete end to end Kotlin tasks, from reading an issue to producing a solution that passes validation. We’re taking the first step in addressing that gap by…

AI & ML3 min read
Astro Blog

Astro 7.0

Astro 7.0 brings faster builds with Vite 8, a new Rust compiler, Advanced Routing, background dev server support, and structured logging.

Web Development13 min read