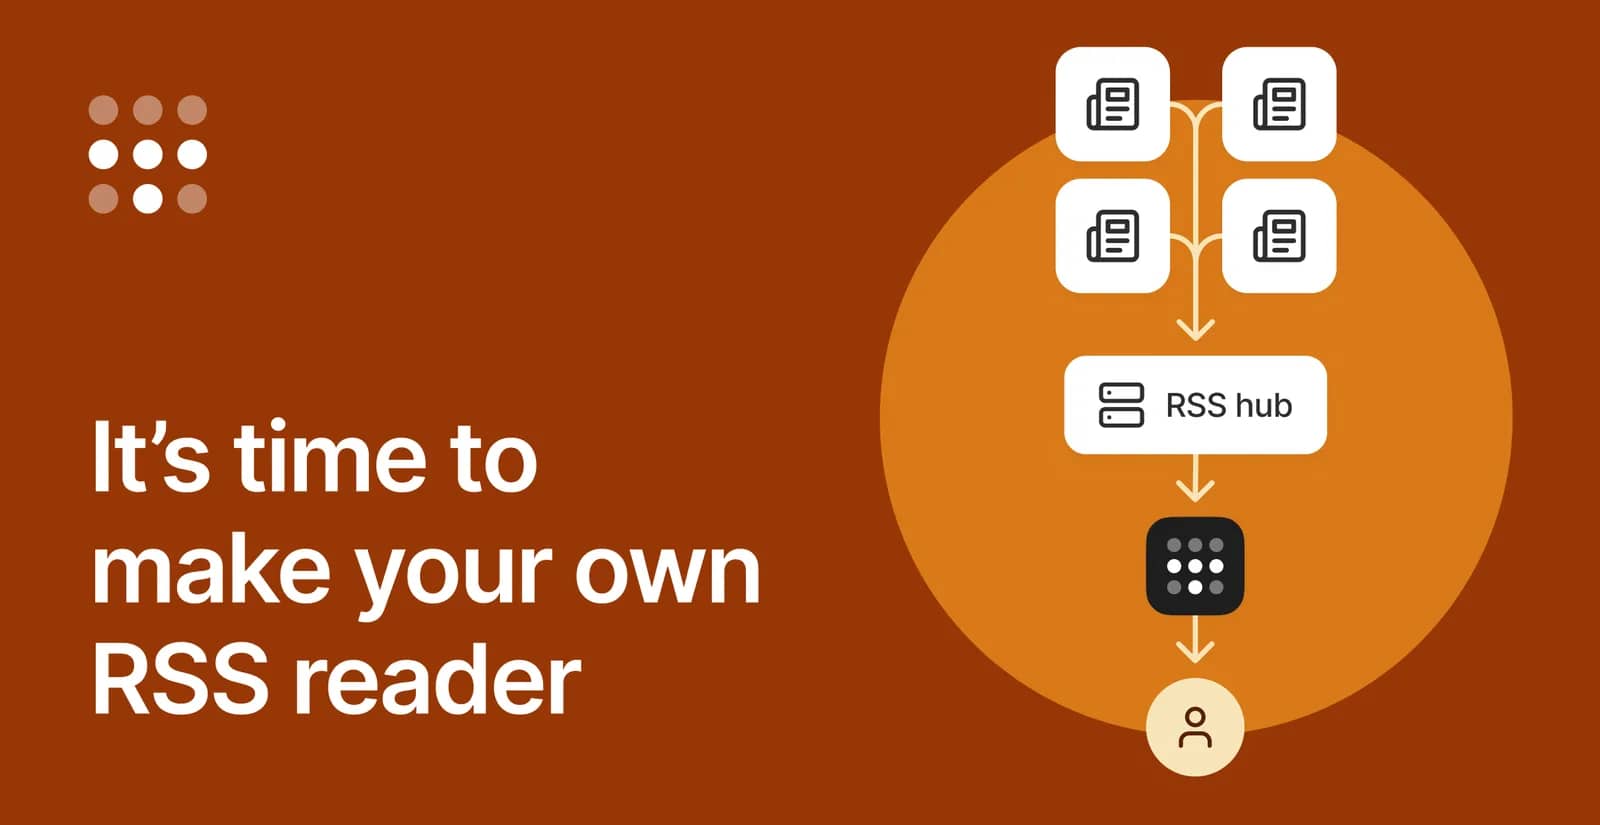
It's time to make your own RSS reader
One RSS reader, on every device you own, no algorithms invited.
ابر و زیرساخت۹ دقیقه مطالعه
برچسب
۴۲ مقاله
One RSS reader, on every device you own, no algorithms invited.
Today, Meta is releasing the weights for Muse Spark Open, the most capable US open weights model to date. It’s available today on Hugging Face under the Muse Model License. Muse... The post Muse Spark 1.2 Is Now Open Weights appeared first on PyTorch .
Learn how the new dotnetup tool helps macOS and Linux developers install, manage, and update user local .NET SDKs and runtimes. The post Introducing dotnetup: A toolchain manager for .NET appeared first on .NET Blog .
TL;DR Deploying PyTorch models on microcontrollers has historically required converting to other framework formats, maintaining separate toolchains, and debugging cross framework numerical mismatches. ExecuTorch eliminates this conversion step entirely. The Cortex M... The post Bringing ExecuTorch to Arm Cortex M…
In August, we launched the $1M hacker challenge for Vercel Sandbox , inviting security researchers to try and escape Vercel Sandbox. We also coordinated with cybersecurity experts Trail of Bits to review the source code and security architecture. Here is a summary of the challenge: 1,285 reports over two weeks…
TL;DR The PyTorch based software stack for IBM’s Spyre accelerator recently moved its torch.compile backend from sendnn, a separate compilation stack built entirely from scratch, to backend=inductor, an open source backend built... The post Extending Inductor for the IBM Spyre Accelerator appeared first on PyTorch .
A customer saw an extra 32 ms on simple SELECT queries after idle periods. We traced it to unbatched Native protocol metadata packets overflowing a reset TCP congestion window, reproduced it with network namespaces, and fixed it by batching them.
Posted by Cyrus Stoller, Group Product Manager, Laptops & Tablets Today, getting the most out of AI workflows requires access to a terminal with a command line, even if someone doesn’t identify as a programmer or software developer. With Googlebook, we’re excited to help users express themselves and gain access to…
Welcome to “What’s new in Swift,” a curated digest of releases, videos, and discussions in the Swift project and community. The Vapor web framework recently turned ten and celebrated with Vapor Week! We’ve invited one of the authors of Vapor as this month’s guest contributor: Hi, I’m Tim from the Vapor Core Team! 10…
TL;DR Spyre becomes a native PyTorch device by connecting PyTorch’s existing device, allocator, stream, and compiler abstractions through torch spyre to the Spyre runtime and firmware. PrivateUse1 gives Spyre a real... The post Building Spyre as a Native PyTorch Device appeared first on PyTorch .
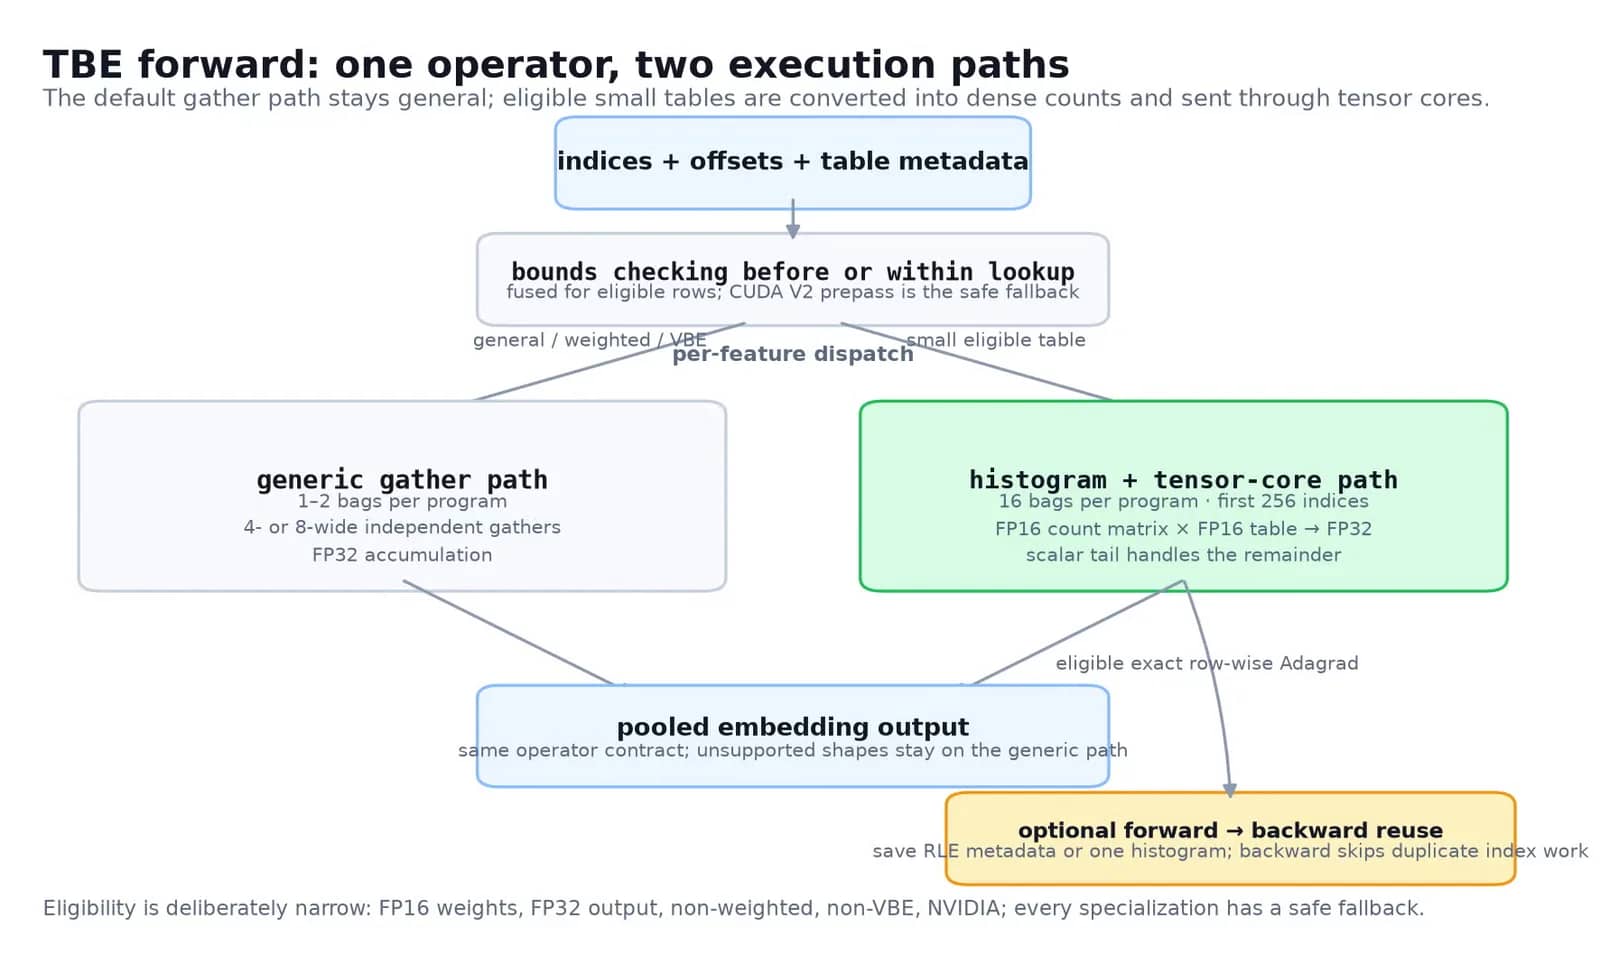
This post explores the FBTriton kernel design for Table Batched Embedding (TBE) forward and backward passes. These core operators handle embedding lookups across thousands of sharded GPUs within recommendation systems.... The post Modernizing Table Batched Embeddings with FBTriton appeared first on PyTorch .
In Linux, cgroups (control groups) are a kernel feature used for managing system resources. Kubernetes uses cgroups to allocate resources like CPU and memory to containers, ensuring that applications run smoothly without interfering with each other. With the release of Kubernetes v1.31, support for v1 cgroup…
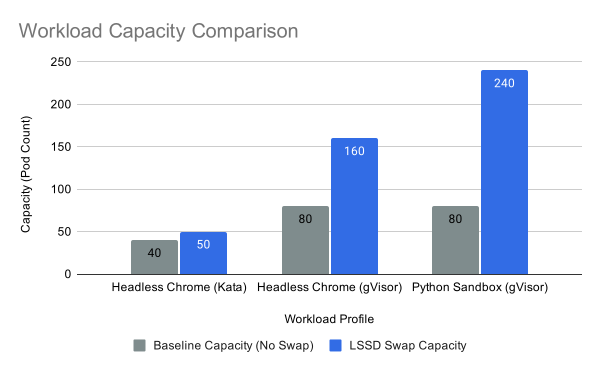
Memory is often the first hard limit a Kubernetes cluster hits. Nodes run out of RAM long before they run out of CPU, and the new wave of agentic AI workloads makes this worse. These workloads demand large memory footprints to start up and run untrusted code, then sit idle waiting for the next prompt. That idle but…
TL;DR We integrated Helion into vLLM’s linear backend to explore how an autotuned, high level kernel DSL can improve LLM inference performance while reducing kernel implementation complexity. A single Helion general... The post Building a High Performance and Portable vLLM Linear Backend with Helion appeared first on…
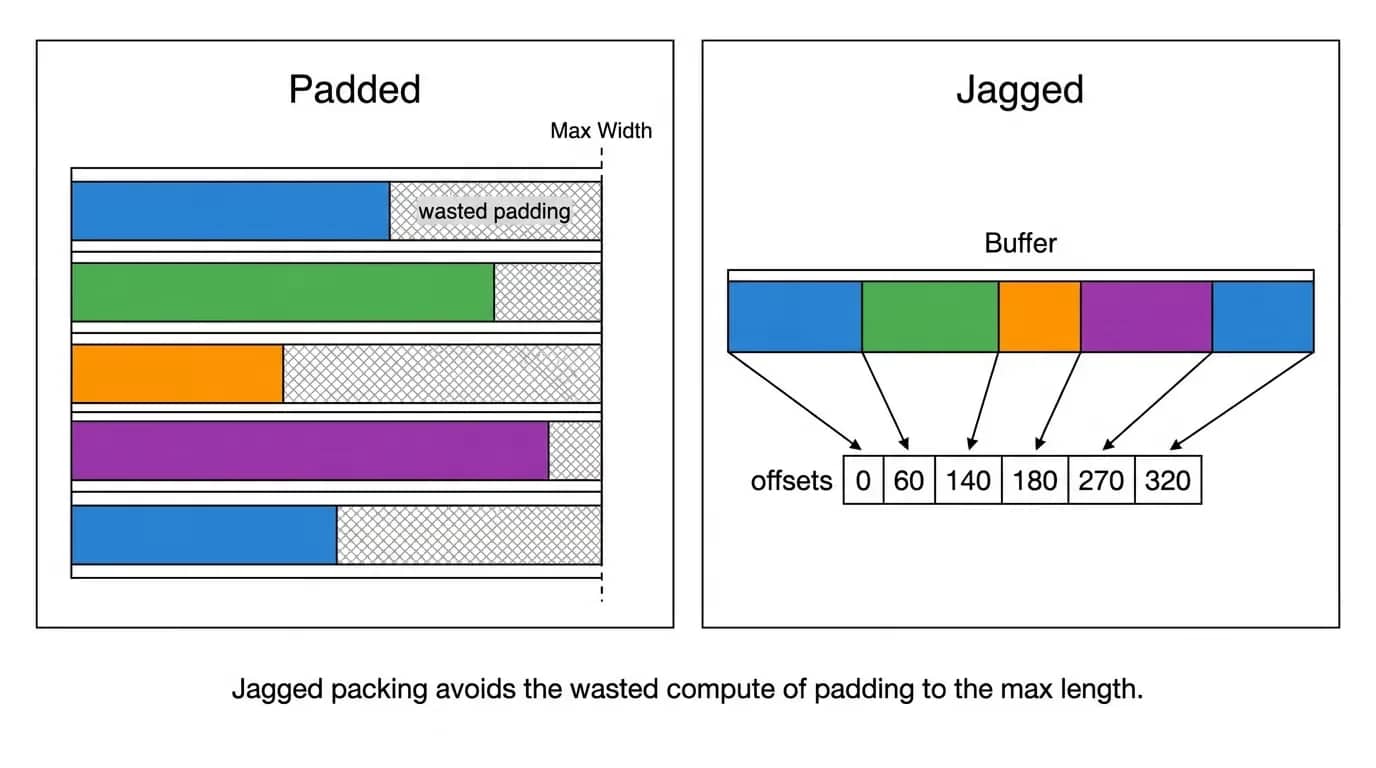
TL;DR In this blog post, we present our work on Jagged Flash Attention (JFA) — the attention kernel behind Meta’s Generative Ads Model (GEM) — on NVIDIA Blackwell (B200), built... The post Optimizing Jagged Flash Attention with TLX: The Road Toward SOTA FA4 on Blackwell appeared first on PyTorch .
Docker's Sandbox Kit Specification v3 packages an AI agent's network rules, credentials, and volumes as an ordinary, pinnable OCI image.
A deep dive into our ongoing commitment to fast and reliable connectivity.
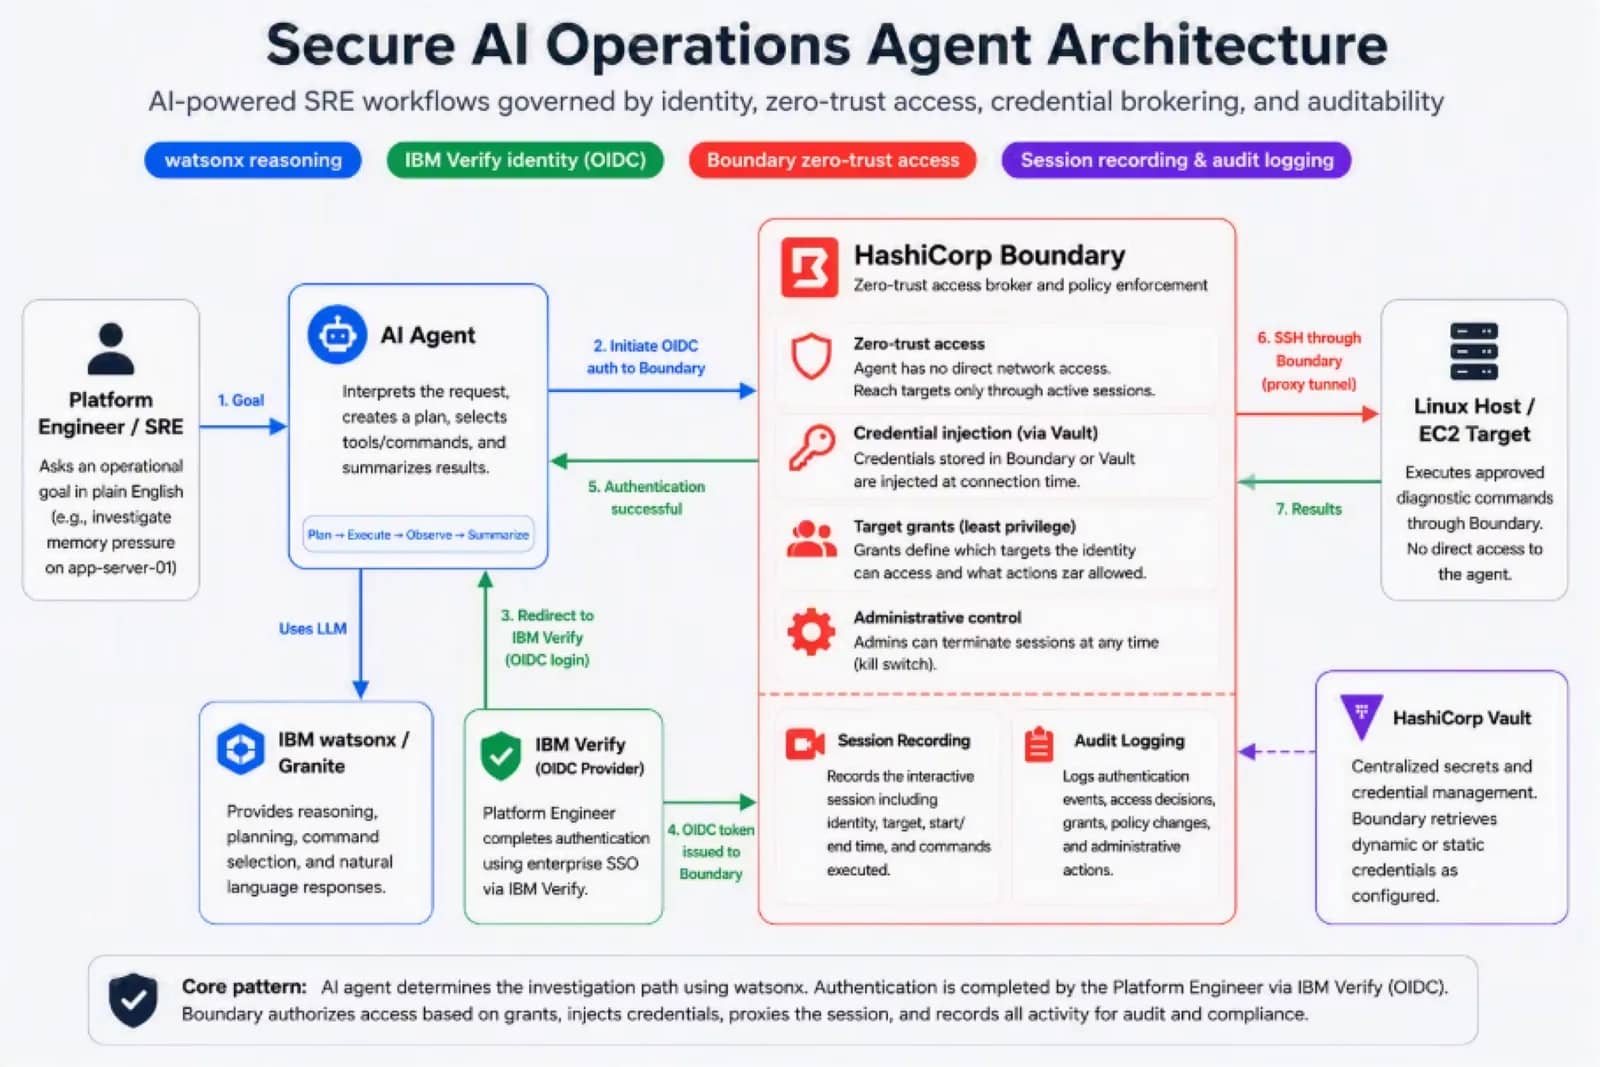
Enable AI agents to securely access your resources while operating within enterprise identity, access, and audit controls.
Kubernetes v1.37 brings important storage security features: emptyDir permission modes and bind mount options. They help application programmers and security professionals implement rigorous security policies, for example, prohibiting deletion of files across containers or execution of arbitrary binaries from…
Memory QoS has graduated to Beta in Kubernetes v1.37 and is now enabled by default. On Linux nodes running cgroup v2, the feature uses the memory controller to give the kernel better guidance on how to treat container memory. It was first introduced as Alpha in v1.22, and expanded in v1.36 with tiered memory…